Let us know how we can help
Sales & Pricing
Speak to a rep about your business needs

Help & Support
See our product support options
General inquiries and locations
Contact us

 Control-M + Tajo
Your Tajo workflow starts before a distributed SQL query ever executes — and it can fail when something upstream breaks. An HDFS partition arrives incomplete. A Spark transformation finishes after its processing window. Control‑M orchestrates the full chain — HDFS data arrival, Spark transformation, and Tajo query execution via Control‑M for Hadoop — through to downstream delivery.
common workflow issues
Does this sound like your week?
HDFS ARRIVAL
Your 02:00 Tajo query starts. The HDFS input is still incomplete.
Control-M’s HDFS File Watcher waits for the required path and minimum file size before releasing the Tajo job. Missing or undersized data keeps execution gated, preventing the query from starting against an incomplete input.
UPSTREAM DELAY
Your Spark transformation runs late. Tajo is already waiting downstream.
Control-M models Spark and Tajo as dependent jobs in the same workflow. The Tajo query waits for successful upstream completion instead of relying on a fixed cron window, keeping execution aligned with actual data readiness
COMMAND FAILURE
An HDFS preparation command fails before the Tajo query even starts.
Control-M runs HDFS pre-commands before Tajo execution and can fail the job when a preparation command fails. The query is stopped before processing compromised inputs, while operators receive a clear job failure to investigate.
QUERY FAILURE
A production Tajo query fails midway through the overnight processing chain.
Control-M captures the job outcome within the wider workflow, prevents dependent processing from advancing, and surfaces the failure for operations. Recovery can be coordinated from the same workflow context instead of tracing failures across separate schedules.
SLA RISK
The query succeeds — but downstream delivery is now trending late.
Control-M tracks Tajo as part of the complete service rather than an isolated query. SLA Management monitors the critical job chain and can surface delay risk before the final delivery deadline is missed.
INTEGRATION FACTS
Control‑M + Tajo
|
workload.types |
Tajo open queries · Tajo input-file jobs · distributed SQL queries · HDFS analytics · batch ETL · ad hoc query execution |
|
trigger.type |
HDFS file arrival · HDFS minimum-size threshold · time schedule · upstream job completion · Control-M event · Automation API submission |
|
cross_tool.deps |
All delivered through Control‑M for Hadoop: HDFS File Watcher · HDFS Commands · Apache Spark · Apache Hive · Sqoop · Java MapReduce · Pig · Oozie workflows · file delivery |
|
cloud.platforms |
On‑premises Hadoop clusters (HDFS) · at least one Control‑M/Agent with Control‑M for Hadoop per cluster · Control‑M SaaS orchestration of the Hadoop cluster |
|
error_handling |
pre-command failure detection · post-command failure handling · downstream dependency gating · job failure alerts · SLA monitoring · controlled recovery |
|
throughput |
distributed SQL workloads · large HDFS datasets · batch ETL · ad hoc analytics · input-file-driven SQL execution |
|
observability |
job execution status · job output · dependency visibility · workflow history · SLA tracking · failure alerts · end-to-end workflow monitoring |
end-to-end orchestration
One production workflow. Every tool in the stack.
Control-M orchestrates workflows across Tajo, HDFS, Spark, Hive, Sqoop, file transfers, and Hadoop services in a single job flow — with dependency tracking, SLA visibility, and automated recovery across all of them.
- Cross-tool dependency: HDFS arrival → Spark transformation → Tajo query → analytics handoff
- Data-aware triggers: HDFS file arrival, minimum file size, upstream job completion, scheduled processing
|
Tajo (a Hadoop job type) |
open‑query execution · input‑file execution · pre/post HDFS commands · |
|
workflow dependencies HDFS |
file arrival watching · minimum-size criteria · HDFS commands · data readiness gating |
|
Apache Spark |
Python execution · Java/Scala applications · upstream transformation orchestration |
|
Apache Hive |
Hive job execution · script parameters · Hadoop workflow dependencies |
|
Sqoop |
command execution · data movement orchestration · dependent processing |
|
Oozie |
workflow execution · job properties · coordinated Hadoop processing |
|
Control-M MFT |
managed file movement · delivery dependencies · downstream workflow triggering) |
airflow coexistance
Control-M doesn’t replace your Airflow DAGs. It runs the layer above them.
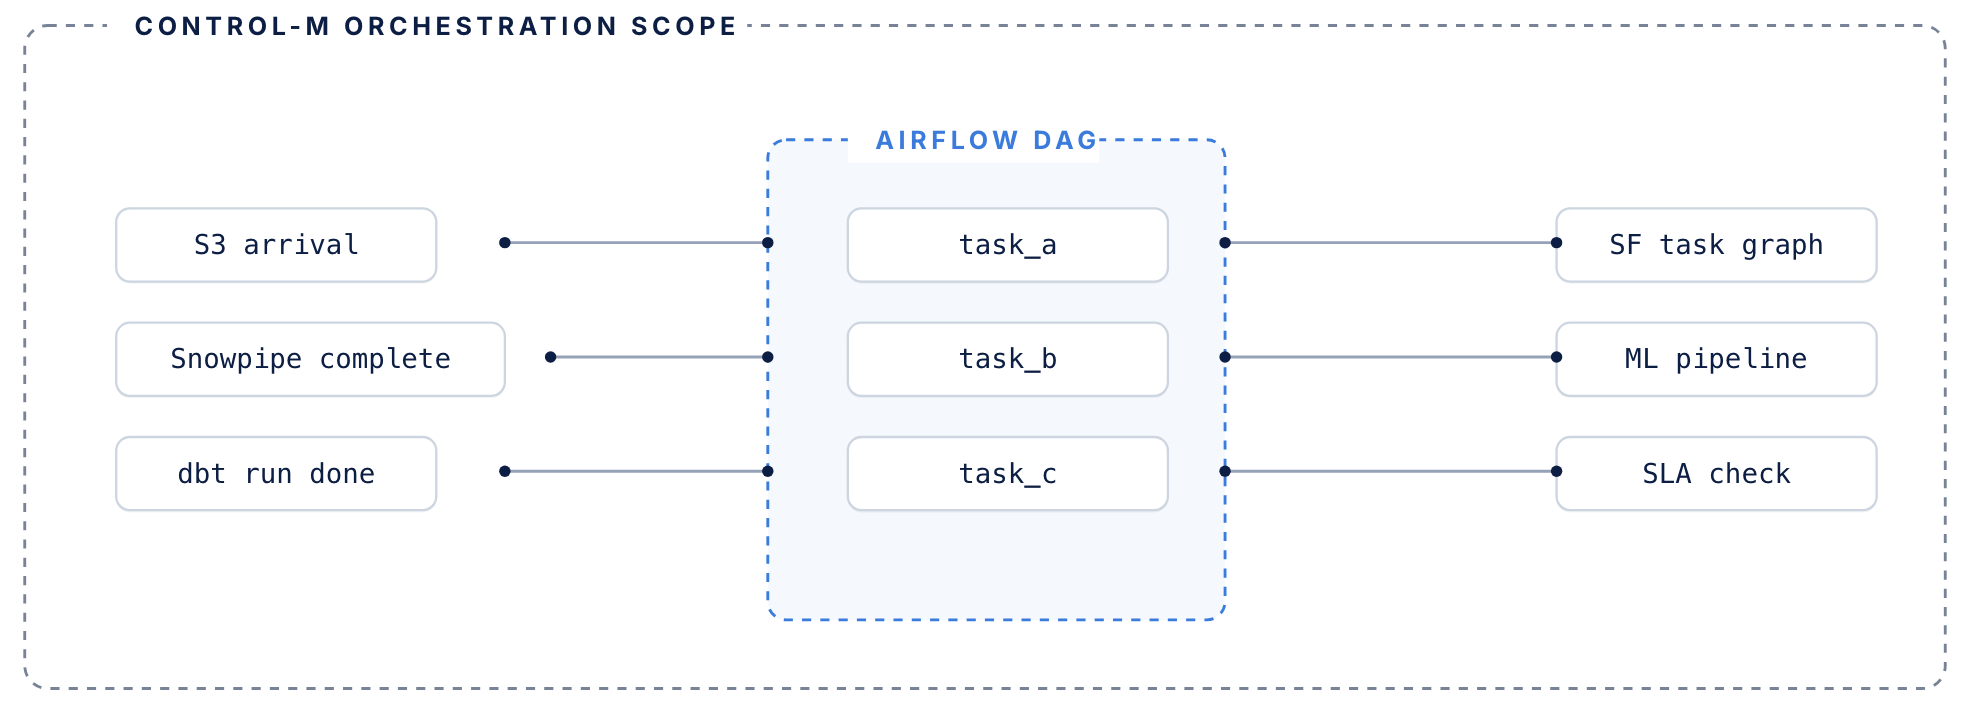
Airflow manages its DAG. Control-M manages everything surrounding it.
airflow handles
DAG-level orchestration inside the data pipeline
- DAG-level task orchestration within data pipelines
- Python operators, sensors, and task dependencies
- Execution graph for jobs that run inside your pipeline
- Manages retries within a single DAG context
control-m adds
The coordination layer around your DAGs
- Coordination layer around DAGs — triggers Airflow based on upstream conditions: file arrivals, API events, other tool completions
- Tracks each DAG’s SLA contribution across the full end-to-end workflow, not just its own routine
- Manages failure recovery when upstream dependencies fail before Airflow even starts
- Existing DAGs don’t need to be rewritten or migrated
MONITOR PIPELINES
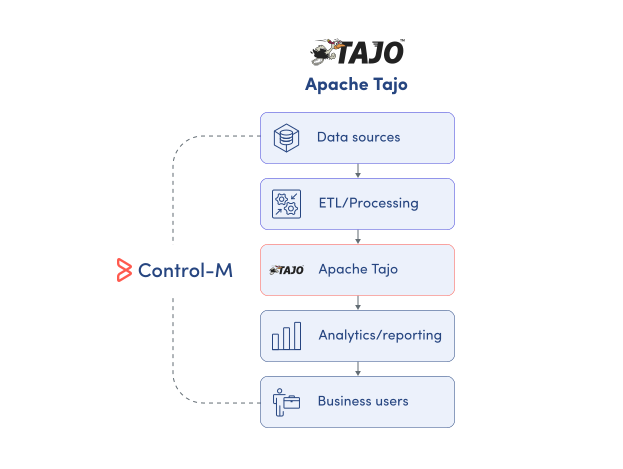
See Tajo execution in the complete data pipeline
Tajo shows what happens inside its distributed query environment; it does not provide the operating view of every external dependency surrounding that query. Control-M connects Tajo execution to the wider production workflow, giving data teams visibility into:
-
Tajo job execution status
-
Upstream and downstream dependencies
-
Job output and failures
-
End-to-end workflow history
-
Cross-platform processing status
SLA ASSURANCE
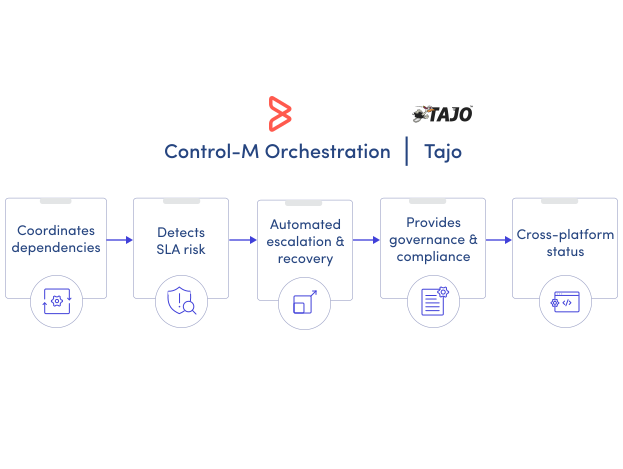
Keep Tajo-dependent data services on schedule
A successful Tajo query can still contribute to a missed delivery when upstream processing starts late or downstream work stalls. Control-M manages the service across the full dependency chain so teams can identify schedule risk before delivery is affected:
-
End-to-end SLA tracking
-
Critical-path dependency visibility
-
Predictive delay detection
-
Automated failure alerts
-
Coordinated downstream recovery
