Let us know how we can help
Sales & Pricing
Speak to a rep about your business needs

Help & Support
See our product support options
General inquiries and locations
Contact us

 Control-M + Hadoop
Your Hadoop workflow starts before a Spark, Hive, or MapReduce job ever executes — and it can fail when something upstream breaks. An expected dataset never lands in HDFS. A Sqoop import from an operational database finishes late. Control-M orchestrates the full chain: HDFS data arrival, Sqoop ingestion, Hadoop execution, and downstream delivery.
common workflow issues
Does this sound like your week?
These aren’t edge cases. They’re the normal operating conditions for teams running Hadoop jobs across multiple tools. Here’s how Control-M handles each one.
HDFS DATA ARRIVAL
Your 2 a.m. Spark job starts. The HDFS input still isn’t there.
Control-M uses file-watching to detect HDFS data arrival and waits for the required data before releasing dependent processing. Spark, Hive, or MapReduce jobs stay gated until the file condition is satisfied, preventing incomplete input from cascading downstream.
INGESTION DELAY
Your Sqoop import runs late. Downstream Hive processing is already waiting.
Control-M tracks Sqoop and Hive in the same workflow and applies dependencies between them. Hive processing starts from actual upstream completion rather than an assumed cron window, eliminating manual checks and brittle schedule offsets.
SPARK FAILURE
Your Spark job fails overnight. Everything downstream needs to stop.
Control-M detects the failed job state and keeps dependent processing from advancing. Recovery logic can be applied before downstream jobs are released, containing the failure instead of letting bad or missing output propagate through the pipeline.
OOZIE COORDINATION
Your Oozie workflow runs long. The downstream delivery window keeps shrinking.
Control-M can extract Oozie workflows and bring their actions into the Control-M scheduling environment. Operations teams can coordinate those jobs with surrounding dependencies and SLA requirements instead of managing the Oozie workflow in isolation.
SLA RISK
Hadoop processing is still running. Your 6 a.m. delivery is at risk.
Control-M connects Hadoop jobs to enterprise SLA management and the wider production workflow. Teams can see how delayed cluster processing affects the delivery deadline and act before a long-running job becomes a missed business SLA.
INTEGRATION FACTS
Control‑M + Hadoop
|
workload.types |
Spark Python · Spark Scala/Java · Pig · Sqoop · Hive · DistCp · HDFS Commands · MapReduce · Oozie |
|
trigger.type |
HDFS file arrival · time schedule · upstream job completion · Control-M event · workflow dependency |
|
cross_tool.deps |
Spark job · Sqoop import/export · Hive job · Oozie workflow · database job · file transfer · downstream application |
|
cloud.platforms |
Hadoop cluster · Linux edge node · Control-M SaaS · Control-M Self-Hosted |
|
error_handling |
pre-command failure handling · post-command failure handling · dependency gating · recovery actions · resource controls · SLA monitoring |
|
throughput |
distributed batch processing · large data sets · cluster execution · distributed copy · Hadoop Streaming |
|
observability |
centralized job monitoring · YARN aggregated logs · execution output · dependency visibility · SLA tracking · job history |
end-to-end orchestration
One production workflow. Every tool in the stack.
Control-M orchestrates workflows across Hadoop, Spark, Hive, Sqoop, databases, file transfers, and cloud services in a single job flow — with dependency tracking, SLA visibility, and automated recovery across all of them.
- Cross-tool dependency: Sqoop → Spark → Hive → analytics handoff
- Data-aware triggers: HDFS file arrival, upstream completion, API event, job status
|
Hadoop |
distributed processing · dependency orchestration · SLA coordination |
|
Spark |
Python execution · Scala/Java execution · application arguments & Spark-submit options |
|
Hive |
query execution · parameters · dependency control |
|
Sqoop |
command execution · imports/exports · workflow sequencing |
|
HDFS |
file watching · HDFS commands · data dependencies |
|
Oozie |
workflow execution · workflow extraction · action coordination |
|
File transfer |
inbound data · outbound delivery · completion dependencies |
airflow coexistance
Control-M doesn’t replace your Airflow DAGs. It runs the layer above them.
The objection is common: “We’re already on Airflow.” The issue isn’t what Airflow does – it’s what happens before and after Airflow runs. That’s where pipelines actually fail.
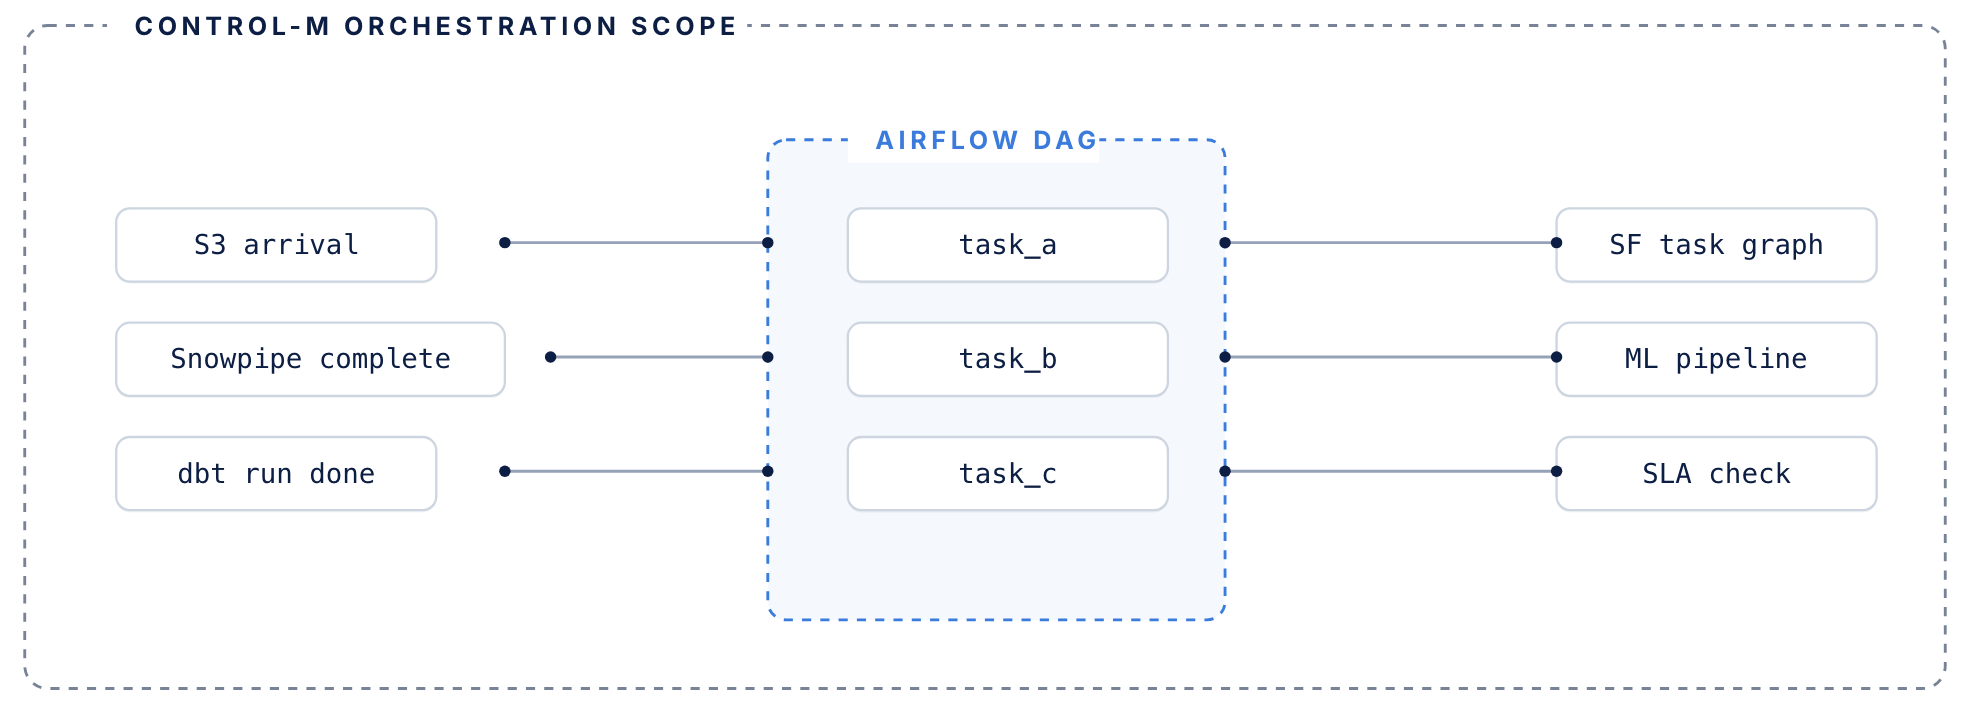
Airflow manages its DAG. Control-M manages everything surrounding it.
airflow handles
DAG-level orchestration inside the data pipeline
- DAG-level task orchestration within data pipelines
- Python operators, sensors, and task dependencies
- Execution graph for jobs that run inside your pipeline
- Manages retries within a single DAG context
control-m adds
The coordination layer around your DAGs
- Coordination layer around DAGs — triggers Airflow based on upstream conditions: file arrivals, API events, other tool completions
- Tracks each DAG’s SLA contribution across the full end-to-end workflow, not just its own routine
- Manages failure recovery when upstream dependencies fail before Airflow even starts
- Existing DAGs don’t need to be rewritten or migrated
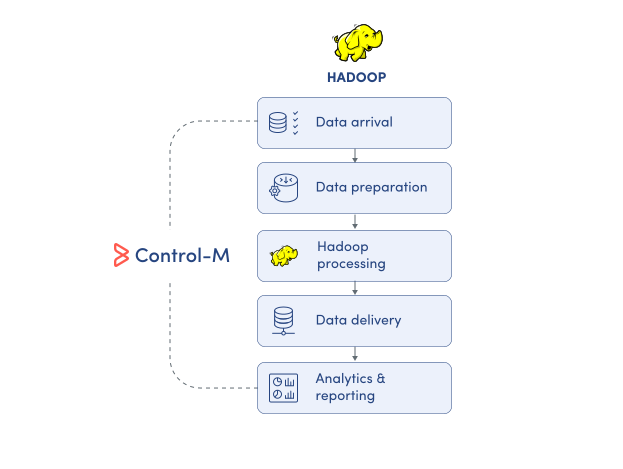
MONITOR PIPELINES
Monitor Hadoop jobs across the complete data pipeline.
Hadoop processing is often only one stage in a production data pipeline. Control-M provides a centralized view across Hadoop and surrounding systems, helping teams follow execution from upstream data arrival through processing and downstream delivery:
-
Hadoop job execution status
-
Job runtime and history
-
Upstream and downstream dependencies
-
Pipeline failure visibility
-
SLA risk indicators
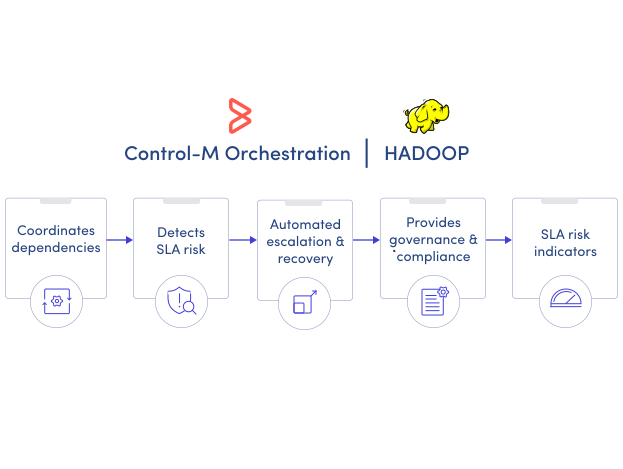
SLA ASSURANCE
Keep Hadoop processing aligned to delivery SLAs.
Native job status tells you whether Hadoop processing ran, not whether the complete business pipeline will finish on time. Control-M connects Hadoop jobs to end-to-end SLA management so teams can identify and address delivery risk:
-
End-to-end SLA tracking
-
Critical-path job visibility
-
Late-running job alerts
-
Dependency-aware downstream control
-
Centralized recovery actions
Documentation
Bring order to complex workflows
Learn how Control-M helps teams orchestrate complex processes with greater visibility, coordination, and control.
